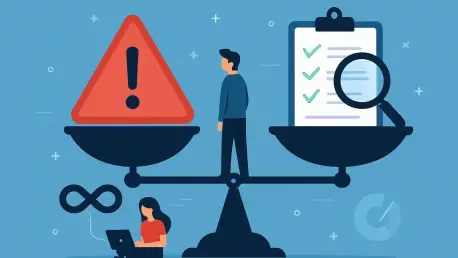
The shift from quantitative metrics to qualitative impact assessment is a necessary survival strategy for maintaining business continuity in hyper-accelerated release cycles. Relying on an arbitrary 100% code coverage target often masks underlying vulnerabilities while consuming disproportionate engineering resources. In the current landscape of 2026, where microservices and serverless architectures dominate, the complexity of interdependencies makes exhaustive testing an impossibility. A team might achieve high coverage scores by testing trivial getter and setter methods while leaving critical transaction logic or third-party API handshakes under-validated. This numerical obsession creates a false sense of security that can lead to catastrophic production failures when edge cases emerge in distributed environments. Engineering leadership now recognizes that high coverage does not equate to high quality; instead, it frequently signals a check-the-box culture that ignores actual business risk. This pivot ensures that testing is treated as a strategic investment rather than a compliance hurdle.
The Coverage Trap: Why Numerical Exhaustion Fails
The traditional reliance on line or branch coverage as a primary KPI has hit a wall as software architectures become increasingly ephemeral and interconnected. When developers are incentivized to meet a specific percentage, they often write low-value tests that confirm obvious logic rather than exploring the unpredictable behavior of a system under load or network instability. This more is better philosophy leads to bloated test suites that take hours to run, significantly slowing down the CI/CD pipeline and frustrating development teams. The resulting lag in deployment frequency contradicts the core tenets of DevOps, which emphasize velocity and responsiveness. Furthermore, massive suites are notoriously difficult to maintain, leading to flaky tests that are eventually ignored, thereby undermining the integrity of the entire automated gatekeeping process. Organizations find that the effort required to increase coverage from 80% to 90% rarely yields a proportional decrease in production incidents, suggesting a point of diminishing returns.
Beyond the mechanical burden of maintenance, the coverage-first mindset fails to account for the qualitative nature of modern software failures, which often occur at the integration boundaries rather than within individual units. A payment gateway might have perfect unit test coverage, but if the asynchronous retry logic for a third-party service is improperly configured, the system will fail under real-world conditions. This discrepancy highlights a critical blind spot in quantitative metrics: they measure what code was executed, not whether that code performs its intended function reliably across a distributed network. As systems move toward autonomous scaling and dynamic resource allocation, the static nature of traditional coverage reports becomes even less relevant. DevOps professionals are pivoting toward observability and chaos engineering as more accurate indicators of system health. By moving away from the coverage for the sake of coverage mantra, teams can reclaim valuable time to focus on exploratory testing and architectural reviews.
Strategic Prioritization: Implementing a Risk-Based Framework
Transitioning to a risk-based testing model requires a systematic approach to identifying which components of an application represent the highest threat to business operations. Utilizing frameworks like Product Risk Management (PRisMA) enables teams to evaluate features based on both the probability of failure and the severity of the impact on the end user. For instance, a bug in an authentication module or a data encryption service carries a significantly higher risk profile than a layout issue on an internal administrative dashboard. By categorizing features into risk quadrants, engineers can apply rigorous, multi-faceted testing—including manual penetration testing and extensive load simulations—to the most critical areas. This targeted application of resources ensures that the crown jewels of the application are protected, while lower-risk sections receive basic automated checks. This strategy acknowledges the reality of finite time and labor, allowing teams to optimize their testing efforts for maximum safety rather than maximum volume.
Furthermore, calculating the Cost of Exposure has become a vital metric for aligning technical testing priorities with executive business goals. This financial analysis compares the potential revenue loss, regulatory fines, and reputational damage of a production failure against the engineering cost of implementing and maintaining exhaustive tests. By speaking the language of risk and return, DevOps teams can justify why they might bypass certain low-impact tests to accelerate a feature launch, or conversely, why a release must be delayed due to insufficient validation of a high-risk transaction engine. This objective methodology removes the gut feeling from release decisions and fosters a culture of transparency between technical and non-technical stakeholders. In 2026, the integration of real-time telemetry data into risk assessments allows for dynamic adjustments to testing strategies. If a particular module shows a high rate of change or frequent regressions in staging, the risk-based model automatically elevates its testing priority.
Human-Centric Automation: The Role of Intelligence and Insight
While artificial intelligence has revolutionized the way teams identify potential regression points, it cannot replace the strategic intuition of human engineers who understand the broader business context. Modern AI-driven testing tools are exceptional at parsing through vast amounts of historical data to predict which files are most likely to contain bugs based on recent commits or complexity scores. These tools can automatically generate test cases for missing edge cases or identify dead code that is falsely inflating coverage metrics. However, an algorithm lacks the ability to understand that a small functional tweak in a legacy module might jeopardize a multi-million dollar partnership or violate a specific regional compliance standard like GDPR. The most successful organizations use AI as a force multiplier, allowing it to handle the monotonous tasks of regression and data generation while human experts focus on higher-order risk assessment. This hybrid approach ensures that the testing strategy is both data-informed and strategically aligned.
Cultivating a collaborative culture is the final piece of the puzzle, as risk cannot be accurately assessed by the QA department in isolation. Effective risk-based testing relies on continuous dialogue between developers, site reliability engineers, and product managers to define what critical truly means for each release cycle. This cross-functional alignment ensures that everyone understands the trade-offs being made when certain tests are prioritized over others. When a development team knows that a specific feature is the primary driver for a quarterly marketing campaign, they can adjust their focus to ensure that the user journey for that feature is bulletproof. This transparency reduces the friction typically found at the end of a sprint, as all parties have already agreed upon the acceptable risk threshold. By fostering this environment of shared responsibility, organizations move away from a defensive blame game and toward a proactive stance on quality. This maturity in the DevOps process allows for more frequent deployments with higher confidence.
Strategic Confidence: Redefining the New Quality Standard
The industry shifted away from the dogma of 100% test coverage because it failed to provide the resilience required for modern, high-velocity software delivery. Engineers recognized that the true measure of a successful QA strategy was the ability to maintain customer trust during rapid iterations. To achieve this, teams implemented a tiered testing approach that prioritized the most sensitive architectural paths, such as identity management and payment processing. They adopted specialized tools like Rapid Risk Assessment (RRA) to provide a standardized language for evaluating technical debt and feature volatility. By integrating these practices, organizations moved beyond the vanity metric of coverage and focused on achieving verifiable confidence in their systems. Moving forward, the focus remained on refining observability and automated rollbacks to mitigate the impact of the inevitable risks that passed through testing gates. The evolution of DevOps necessitated that developers became risk managers, balancing the speed of innovation with the stability of the core business environment.
Ultimately, the transition to risk-prioritized testing allowed for more sustainable development cycles and a significant reduction in the frequency of high-severity production incidents. DevOps teams learned to embrace the fact that perfection was an unattainable goal in distributed cloud environments and instead focused on protecting the user experience. They established robust feedback loops between production monitoring and the testing pipeline, ensuring that real-world failures directly informed future risk assessments. This shift fostered a more resilient engineering culture where developers felt empowered to prioritize meaningful work over meeting arbitrary numerical targets. The adoption of chaos engineering principles further strengthened the system’s ability to handle unforeseen failures gracefully. As a result, the industry reached a state of maturity where software reliability was measured by business outcomes rather than code execution percentages. These strategies ensured that even as release frequencies increased, the stability and security of critical infrastructure remained uncompromised.