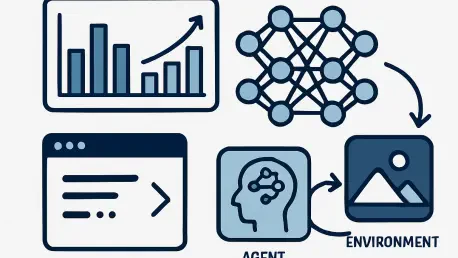
Evaluating a policy with the evaluate_policy helper provides a streamlined way to calculate the mean reward across multiple episodes without manual loop construction. This capability sits at the heart of Stable-Baselines3, a library that has fundamentally transformed how researchers and developers approach reinforcement learning. By moving away from the brittle, custom-coded implementations of the past, the community has embraced a modular framework that prioritizes reliability and performance. As machine learning architectures become more complex in 2026, the need for standardized benchmarks is paramount. Stable-Baselines3 offers a unified API that bridges the gap between theoretical research and practical application. It allows users to focus on the nuances of reward shaping and environment design rather than the underlying calculus of gradients. This guide serves as a comprehensive roadmap for navigating the installation, execution, and validation of intelligent agents, ensuring every experiment is grounded in consistency and rigor.
1. Defining the Core Utility: Understanding the Library
Stable-Baselines3 represents a sophisticated evolution in the PyTorch ecosystem, serving as the reliable successor to previous iterations. It provides a robust collection of open-source algorithm implementations released under the permissive MIT license, ensuring accessibility for both academic and commercial pursuits. Researchers utilize this library to deploy standard agents such as PPO, SAC, and DQN within environments that adhere to the Gymnasium interface. This standardization is critical because it allows for direct comparisons between different training methodologies without the noise of varying implementation details. By offering a consistent API, the library reduces the cognitive load on developers, enabling them to swap algorithms with minimal code changes. Such flexibility is essential when testing whether a specific problem is better suited for off-policy methods like Soft Actor-Critic or on-policy approaches like Proximal Policy Optimization. This structural integrity ensures results are not just artifacts of code.
The ecosystem is organized into distinct packages to balance stability with innovation. The core Stable-Baselines3 package houses battle-tested algorithms like A2C, DDPG, and TD3, which are benchmarked against reference codebases to guarantee high unit test coverage. Beyond the core, the SB3-Contrib package acts as a repository for experimental features, including RecurrentPPO and Maskable PPO, which are vital for handling partially observable environments or discrete action masks. For those seeking the performance benefits of accelerated linear algebra, the SBX extension introduces JAX-based implementations like CrossQ and SimBa. This tiered approach allows users to choose between the rock-solid reliability of the core library or the cutting-edge speed of JAX-based modules. Consequently, the framework supports a wide spectrum of research needs, from traditional robotics simulations to the latest developments in generative agent behavior. Each package maintains the same design philosophy, ensuring that skills learned in one area translate seamlessly to others in the RL stack.
2. Technical Setup: Installation Procedures and Environment Requirements
Successful deployment of reinforcement learning agents starts with a precise environment configuration that meets modern software standards. As of late 2026, Stable-Baselines3 requires a minimum of Python 3.10 and PyTorch 2.8 to function correctly, taking advantage of recent optimizations in tensor processing. On Windows systems, utilizing a conda-style environment like Miniforge is highly recommended to manage complex dependencies effectively. The installation process is typically handled via pip, where a full installation including TensorBoard and environment-specific extras is achieved using a specialized command string. It is important to remember that when using shells like zsh, the package specification must be enclosed in single quotes to prevent the terminal from misinterpreting the bracketed extras. A basic installation is also available for those who only require the core algorithm logic without additional visualization tools. Ensuring these foundational requirements are met prevents the majority of common runtime errors that plague early-stage development and experimentation.
Advanced users often require configurations tailored for high-performance computing clusters or containerized environments. When operating on headless machines or within Docker containers, the standard OpenCV build may cause display errors, making the installation of the headless version of the package a necessary step. The official Docker images provided by the project serve as a robust base, but a common pitfall is the assumption that the SB3 library is pre-installed. In reality, these images are designed for development flexibility, requiring the user to install the specific version of the package needed for their project inside the container. For those who wish to contribute to the codebase or access the latest experimental patches, cloning the repository and performing an editable installation is the preferred path. This method allows for the inclusion of documentation and testing suites that are not bundled with the standard distribution. By following these structured installation paths, developers can ensure their local and remote environments remain synchronized for seamless transitions.
3. Workflow Implementation: Training and Persistence Strategies
The process of training an agent begins with the initialization of the task through the Gymnasium interface, often using standard benchmarks like the CartPole environment. Once the environment is established, the developer instantiates the model by selecting an algorithm and a policy architecture, such as a Multi-Layer Perceptron. For instance, creating an A2C model involves passing the policy type and the environment to the class constructor, where enabling verbose output provides real-time feedback on training progress. The actual learning phase is triggered by a simple method call where the total number of timesteps is specified, allowing the agent to interact with the world and refine its policy. During this phase, the library handles the complex cycles of observation, action selection, and backpropagation internally. This high-level abstraction allows the user to focus on higher-order concerns like the convergence rate and the stability of the loss functions. Training a model is thus transformed from a manual coding chore into a strategic configuration task.
After training is complete, the focus shifts to running the trained policy and ensuring it can be persisted for future use. Executing the agent involves obtaining the vectorized environment and running a prediction loop where the model generates actions based on incoming observations. It is generally recommended to use deterministic actions during the testing phase to assess the true performance of the learned policy. Saving the model is straightforward, as the library provides a method that bundles the neural network weights and configuration into a single archive file. This saved state can be reloaded later using the class-level load method, which is particularly useful for resuming training or deploying the agent into a production environment. However, it is vital to note that loading a model does not perform an in-place update of an existing instance; rather, it creates a new object with the restored parameters. This distinction is crucial for maintaining proper object references in more complex software architectures. Efficient persistence ensures that the time-intensive process of training is never lost.
4. Performance Metrics: Evaluation and Ensuring Reproducibility
Quantifying the success of a reinforcement learning experiment requires more than just a cursory glance at training logs; it demands rigorous evaluation. The built-in evaluation helper is designed to calculate the mean and standard deviation of rewards over a specified number of episodes, providing a statistically sound measure of performance. A critical step in this process is the use of the Monitor wrapper, which should be applied to the environment before any other wrappers. This ensures that the rewards and episode lengths recorded are the original, unmodified values, preventing any downstream transformations from skewing the final metrics. Evaluation is typically performed with a deterministic policy to eliminate the variance associated with action sampling, though stochastic evaluation is possible if the research context requires it. By wrapping the environment correctly, developers gain access to detailed rollout data that is essential for identifying whether an agent has truly mastered the task or has simply found a way to exploit a specific reward signal.
Reproducibility is the cornerstone of scientific progress, and Stable-Baselines3 provides several mechanisms to facilitate this. A saved model archive contains not just the policy weights, but also the optimizer state and system metadata, including the library version and hardware info. When documenting a methods section for a report or paper, it is imperative to record the specific versions of Python and PyTorch used, along with the total training timesteps and hyperparameter settings. Since the library uses cloudpickle for serializing certain objects, maintaining the same Python version across training and deployment environments is necessary to avoid compatibility issues. Users should also leverage the system info logging feature during the loading process to verify that the environment matches the one where the agent was originally conceived. This level of detail ensures that other researchers can replicate the results accurately, fostering a culture of transparency and trust within the AI community. Without such rigorous documentation, the subtle nuances of agent behavior might be lost.
5. System Refinement: Troubleshooting and Future Considerations
Encountering hurdles during the development cycle is common, but most issues in the library can be resolved through systematic checks. Version conflicts are the most frequent culprit, often occurring when the system’s Python or PyTorch installations fall behind the required specifications. In zsh environments, the “no matches found” error can be particularly frustrating, yet it is easily fixed by properly quoting the installation strings. If a model fails to load or behaves unexpectedly, the first step should always be to compare the system information of the saving and loading environments. Discrepancies in library versions can lead to subtle bugs that are difficult to trace without the built-in diagnostic tools. Furthermore, if the evaluation rewards appear inconsistent with the training logs, the developer must verify that the Monitor wrapper was applied as the first layer of the environment stack. These troubleshooting steps form a vital part of the development workflow, ensuring that the time spent on training leads to valid and actionable insights.
The journey of building a reinforcement learning agent concluded with a focus on future scalability and experimental refinement. Developers moved beyond basic training loops to embrace specialized packages like SB3-Contrib and JAX-powered extensions for more demanding tasks. By mastering the installation and evaluation pipeline, the groundwork was laid for exploring complex reward shaping and curriculum learning. The integration of TensorBoard allowed for deep dives into value loss and gradient stability, providing the necessary data to fine-tune neural network architectures. As the field evolved from 2026 into the following years, the emphasis shifted toward more robust and interpretable models. The systematic approach to saving and documenting experiments ensured that every iteration contributed to a growing body of knowledge. Future considerations now involve the deployment of these agents into real-world robotics and autonomous systems, where the reliability established in simulation is put to the ultimate test. Through disciplined practice and rigorous validation, the potential for intelligent agents to solve intricate problems became more achievable than ever before.