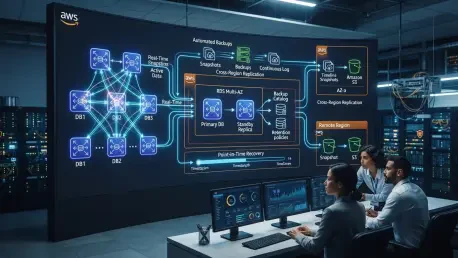
Enterprise teams frequently struggle with the 100-snapshot-per-region limit, a ceiling that often triggers backup failures during high-frequency retention cycles. When managing a sprawling AWS estate, the difficulty of data protection shifts from the technical act of taking a backup to the logistical nightmare of ensuring every single instance in every account is covered. In a multi-account environment, the visibility gap often leads to unprotected databases lurking in shadow IT projects or rapidly scaled dev-test accounts. Professional teams now require a centralized mechanism that not only automates the snapshot process but also provides a way to extract specific records without performing a full-instance restore, which is both time-consuming and expensive. The ability to verify backups through automated restore testing has become a standard requirement for audit compliance, replacing the old method of manual checks and hopeful assumptions. As data volumes grow between 2026 and 2028, the need for logical air-gapping and immutable storage has moved from a niche security request to a core infrastructure necessity to defend against sophisticated ransomware that targets cloud credentials.
1. Eon: Scaling Beyond Manual Discovery
Eon represents a significant shift in cloud data management by moving away from the brittle reliance on manual resource tagging. This platform provides Cloud Backup Posture Management that continuously scans the AWS environment to discover new RDS and Aurora instances as they are deployed. By automatically classifying data based on its sensitivity—such as identifying PII or financial records—the system can apply the correct backup policy without requiring manual intervention from a database administrator. This level of automation is essential for organizations managing hundreds of accounts where human error in tagging is a statistical certainty. The platform connects via a read-only IAM role, ensuring that the integration process does not introduce unnecessary security overhead or require complex agent installations that could impact database performance during peak traffic periods.
The granular recovery capabilities of Eon set it apart in a market where full instance restores are the default. Instead of waiting hours to spin up a copy of a multi-terabyte database just to find a handful of deleted rows, users can perform restores down to the table or even the row level using SQL-based queries. This efficiency drastically reduces the Recovery Time Objective (RTO) for common data corruption scenarios. Furthermore, the solution offers a logically air-gapped vault in a dedicated account, providing a final line of defense against credential compromise. By fingerprinting tables and performing periodic integrity checks, the system ensures that the data being backed up is actually restorable, providing a level of assurance that standard native snapshots cannot match. This approach allows enterprises to maintain high-frequency point-in-time recovery while archiving older data into cost-effective, immutable storage.
2. N2WS: Managing Disaster Recovery via Virtual Appliances
N2WS remains a popular choice for teams that prefer to maintain backup orchestration within their own AWS perimeter rather than using a fully managed SaaS provider. Delivered as a Linux-based virtual appliance from an AMI, this tool gives infrastructure teams complete control over the backup server and its configuration. It excels at complex cross-Region and cross-account disaster recovery workflows for RDS and Aurora, including specialized support for Aurora Serverless. With the ability to schedule backups as frequently as every sixty seconds, it caters to high-transaction environments where data loss of even a few minutes is unacceptable. The platform’s ability to orchestrate these snapshots across dozens of accounts from a single management console provides the centralized visibility that large-scale AWS Organizations require to maintain their security posture.
The pricing model of N2WS is particularly attractive for large-scale fleets with high data growth projections for the 2026-2028 cycle. By charging a flat monthly subscription based on the number of protected instances rather than the total volume of data, it allows for more predictable budgeting as database sizes expand. For long-term retention, the software can export RDS snapshots to an S3-based repository that utilizes S3 Object Lock for immutability. This process uses the AWS snapshot export to Parquet, which is currently compatible with MySQL and PostgreSQL engines. While this adds a layer of complexity compared to integrated SaaS solutions, it provides the “own your own data” architecture that many highly regulated financial and healthcare institutions demand. Maintenance of the appliance, including patching the underlying OS and managing server uptime, remains the responsibility of the customer’s internal operations team.
3. AWS Backup: Leveraging the Power of Organizations
AWS Backup serves as the native foundational layer for policy-driven data protection within the Amazon ecosystem. By integrating directly with AWS Organizations, it allows a central IT team to define backup plans that are automatically propagated across all member accounts, ensuring that no database is left without a safety net. This tool manages the creation of manual snapshots and orchestrates continuous backups for point-in-time recovery with one-second precision. One of its most powerful features is the cross-account copy functionality, which allows snapshots to be moved into a separate, isolated account within the same organization. This physical separation is a critical step in building a resilient disaster recovery strategy that can withstand the total compromise of a primary production account.
The introduction of AWS Backup Vault Lock has significantly enhanced the platform’s security capabilities for enterprise users. In compliance mode, this feature prevents anyone—including the root user or AWS support—from deleting recovery points before their retention period expires. This immutability is vital for meeting regulatory requirements and protecting against malicious insiders. Additionally, the platform includes Backup Audit Manager, which provides a dashboard for monitoring compliance against organizational policies and generating reports for auditors. While it lacks the row-level restore granularity of more specialized third-party tools, its seamless integration with the AWS console and pay-as-you-go pricing makes it the default starting point for any team. As of late 2026, the service continues to expand its support for different database engines, making it a reliable, if basic, choice for standard instance-level recovery.
4. Veeam: Bridging the Gap Between VMs and Databases
Veeam has successfully transitioned its deep expertise in on-premises virtualization to the cloud through its specialized AWS plug-in. This solution is ideal for enterprise teams that still maintain a significant footprint in the data center while aggressively expanding their RDS and Aurora usage in AWS. By providing a unified console that manages both cloud-native snapshots and traditional image-level backups, it reduces the cognitive load on backup administrators who otherwise would have to jump between multiple disparate tools. For RDS instances running SQL Server or PostgreSQL, the plug-in can perform image-level backups into Amazon S3, enabling database-level restores that are much faster than rebuilding an entire instance from a standard snapshot. This hybrid approach allows for a more flexible recovery strategy depending on the nature of the data loss.
The architecture of the Veeam solution relies on temporary worker instances that spin up in the production account to handle data movement and then terminate once the job is complete. This ensures that no long-running agents are needed within the database environment itself, maintaining the performance benefits of a managed service. While engines like MySQL and Oracle are currently limited to snapshot-based protection, the PostgreSQL support covers versions up to 17, catering to the latest enterprise deployments. The licensing model is based on the Veeam Universal License, which allows for portability across different environments, making it a strategic choice for organizations that may need to shift workloads between clouds or back to on-premises servers. The management of the backup appliances and the underlying networking, including VPC DNS and security groups, does require more hands-on configuration compared to a SaaS-only model.
5. DruvAdopting a Zero-Infrastructure SaaS Model
Druva offers a distinct advantage for teams that want to eliminate the operational burden of managing backup infrastructure. As a fully managed SaaS platform, there are no appliances to patch, no storage to provision, and no scaling issues to solve manually. The solution is split into two primary components: CloudRanger for snapshot orchestration and RDS Airgap for decoupled data storage. The Airgap feature is particularly noteworthy because it moves the backup data entirely out of the customer’s AWS Organization and into Druva’s secure cloud environment. This architecture provides an inherent layer of protection against account-level ransomware attacks, as a compromised AWS root credential would still be unable to reach the backups stored within the Druva ecosystem.
The SaaS delivery model of Druva allows for a simplified disaster recovery workflow where DR plans can be tested and executed with a few clicks. Between 2026 and 2028, many organizations are expected to prioritize this “zero-footprint” approach to reduce their internal maintenance costs and focus their engineering resources on product development rather than infrastructure management. The platform also includes features like Data Lock, which ensures that recovery points are immutable and cannot be altered even by Druva’s own administrative staff. While teams must be aware of engine-specific limitations—such as the requirement for customer-managed KMS keys for certain air-gapped copies—the overall ease of use makes it a strong contender for SaaS-first enterprises. The unified dashboard provides a clear view of the protection status across multiple cloud accounts, simplifying the reporting process for security and compliance teams.
6. Commvault and Clumio: Navigating Regulated Data Archives
Commvault has fortified its cloud-native offerings through the integration of Clumio, providing a robust solution tailored for highly regulated industries like finance and government. This platform is designed to handle the long-term retention requirements that often exceed the 35-day limit of native AWS point-in-time recovery. It offers different storage tiers, such as SecureVault Standard for short-term needs and an Archive tier for data that must be kept for years. One of the standout features is the ability to perform record-level retrieval from the Archive tier. This allows administrators to extract specific data points without having to restore an entire database, which is particularly useful for responding to legal discovery requests or localized data corruption incidents that only affect a small subset of records.
The cost-efficiency of the Clumio Archive tier is a major draw for enterprises managing petabytes of historical data. By utilizing a pay-per-GB model with tiered pricing, organizations can significantly reduce their storage costs compared to keeping manual snapshots in primary RDS storage. The platform supports a wide range of engines, including Oracle SE2 and Enterprise Edition, as well as MariaDB and Aurora. However, users must account for a “thaw” period when retrieving data from the deep archive, which can take up to 48 hours. This trade-off between retrieval speed and storage cost is a core part of the platform’s value proposition for long-term compliance. The ability to manage these different tiers under a single policy engine ensures that data moves through its lifecycle automatically, reducing the risk of human error in managing retention periods.
7. Rubrik: Securing Multi-Cloud Estates via SLA Policies
Rubrik positions itself as a security-first data management platform, focusing on the protection and recovery of data across mixed on-premises and multi-cloud environments. Its RDS protection is built around the concept of SLA policies, which define the backup frequency, retention period, and target location for data in a way that is consistent across the entire enterprise. This policy-driven approach allows security teams to enforce a uniform standard of protection regardless of where the database is hosted. By providing a single console for both AWS and other cloud providers, Rubrik eliminates the silos that often lead to inconsistent backup coverage and hidden security vulnerabilities. The integration process is handled through cross-account IAM roles, avoiding the need for permanent credentials and simplifying the onboarding of new accounts.
The Managed Cloud Protection model offered by Rubrik is designed to provide a turnkey vaulting solution where the platform handles both the compute and the storage in an environment separate from the production accounts. This setup includes Object Lock by default on every backup, ensuring that data is immutable from the moment it is created. While the platform is heavily focused on cyber recovery and ransomware detection, it also maintains the standard functionality required for day-to-day operations, such as point-in-time recovery for transaction logs. The emphasis on data integrity and “clean” recovery points makes it a preferred choice for organizations that view data protection as a core component of their cybersecurity strategy. As organizations move through the 2026-2028 timeframe, the integration of AI-driven insights into backup health and recovery readiness is expected to become a key differentiator for the Rubrik ecosystem.
8. Amazon RDS Automated Backups: Maintaining the Fundamental Layer
Amazon RDS automated backups serve as the critical baseline that every AWS user should utilize, as they are integrated directly into the service and require no third-party configuration. This layer captures daily snapshots of the entire instance and continuously archives transaction logs to S3, enabling point-in-time recovery to any second within the retention window. Because the initial storage for these backups is free up to 100% of the provisioned database size, it represents the most cost-effective way to provide immediate protection for every instance. Aurora clusters take this a step further with continuous backups that cannot be disabled, ensuring that the latest restorable time is typically within five minutes of the current time. This level of protection is essential for operational recovery from accidental deletions or software bugs.
Despite its utility, the native layer has structural limitations that necessitate the use of the more advanced tools mentioned earlier. The 35-day retention cap for automated backups means that any organization with a longer compliance requirement must manually manage snapshots, which can quickly lead to account-level quota issues. Additionally, the native system does not provide cross-account isolation by default, meaning that a compromise of the production account could lead to the deletion of all backups. However, features like Aurora Backtrack allow users to “rewind” a database cluster to a previous point in time without performing a full restore from a snapshot, which can be a lifesaver during a failed schema migration or data corruption event. Every enterprise strategy should start by ensuring this native layer is correctly configured before layering on more complex orchestration and vaulting solutions to fill the remaining gaps.
9. A Systematic Approach: Executing a Global Rollout Strategy
Implementing a robust RDS backup strategy across a large enterprise requires a disciplined, multi-step approach to avoid common pitfalls. The first step was to identify and rectify the default retention settings on all existing instances, as many databases created via the API only keep backups for a single day. Following this, the administration team established a baseline policy using AWS Backup at the Organization level. This ensured that every new account automatically inherited a minimum set of protection rules, creating a safety net that caught instances before they could become a liability. By centralizing this policy management, the organization was able to provide proof of coverage to auditors without having to log into hundreds of individual accounts to verify settings manually.
Once the baseline was established, the focus shifted to isolating critical data and enhancing the speed of recovery for high-value assets. Long-term snapshots were moved into immutable vaults or dedicated security accounts, providing a physical and logical barrier against ransomware. The team then integrated advanced tools to enable record-level recovery for databases where a full restore would be too slow to meet the business’s needs. Regular restore drills were scheduled and documented, turning the recovery process from an emergency fire drill into a routine operational task. This systematic progression from basic visibility to advanced isolation and granular recovery allowed the organization to scale its cloud presence securely and confidently, ensuring that the data protection strategy evolved alongside the growth of the underlying infrastructure.
10. Common Queries: Addressing Technical and Operational Constraints
Organizations often ask how they can effectively manage RDS backups across hundreds of AWS accounts without overwhelming their engineering teams. The answer lies in combining the broad reach of AWS Organizations with specialized discovery tools that can detect and protect databases as soon as they are created. While native tools provide the foundation, third-party platforms add the necessary automation to handle the sheer volume of accounts. Another frequent concern is whether tools like N2WS require significant maintenance. Since these tools run as virtual appliances in the customer’s own account, the customer is responsible for the underlying infrastructure, which some teams prefer for security reasons, while others see it as an unnecessary overhead compared to a SaaS model.
The technical nuances of cross-Region recovery also remain a point of discussion, particularly regarding point-in-time recovery. While AWS Backup can replicate snapshots across Regions, the continuous transaction log history usually remains in the source account unless specific RDS-level cross-Region features are enabled. This distinction is critical when designing a disaster recovery plan that requires high-precision recovery in a secondary location. Furthermore, the support for Aurora clusters varies significantly between providers, with some offering full cluster-level protection and others focusing on individual instances. Teams must carefully evaluate whether their chosen tool supports the specific versions and configurations of the database engines they use, particularly as newer versions are released and adopted between 2026 and 2028.
11. Next Operational Steps: Moving Toward Validated Recovery
In the period leading up to the present, enterprise teams have successfully moved beyond the era of manual snapshot management. The focus shifted from simply creating backups to ensuring that every recovery point was immutable, isolated, and, most importantly, verified. Organizations that adopted a layered approach—using native tools for speed and third-party platforms for scale and security—saw a dramatic reduction in their data loss incidents. The implementation of automated restore testing proved to be the most significant improvement in data reliability, as it caught configuration errors and data corruption before they could impact a real recovery effort. This proactive stance on data integrity allowed infrastructure teams to provide the high levels of availability that modern digital businesses demand.
Moving forward, the primary recommendation for infrastructure leads was to conduct a comprehensive audit of their cross-account backup architecture. By identifying any recovery points that still resided within the same credential boundary as production, teams were able to close the most dangerous gap in their security posture. The transition to record-level retrieval for mission-critical databases also paid dividends by reducing the RTO for minor data issues from hours to minutes. As the complexity of cloud environments continued to increase, those who prioritized a unified, policy-driven protection strategy were the ones who maintained operational stability. This strategic investment in modern backup technology ensured that the data assets of the enterprise remained a source of value rather than a significant risk.