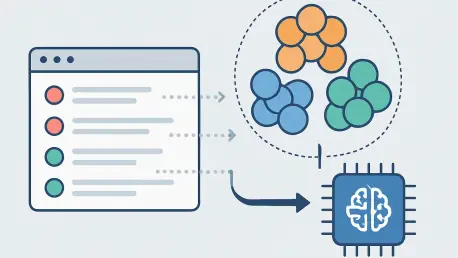
The relentless accumulation of failed test reports in a continuous integration pipeline often forces engineering teams to waste their most productive morning hours on manual data entry and repetitive classification tasks. In modern software development, these high-volume test suites frequently generate a massive amount of noise that demands significant manual effort to resolve. Transitioning from tedious manual triage to an automated system allows organizations to use generative intelligence and clustering to categorize failures, identify root causes, and provide actionable summaries. By following these best practices, teams can reduce the overhead of regression runs and focus on genuine product defects rather than environmental instability.
The automation of this process ensures that developers spend their energy fixing bugs rather than sorting through redundant datasets. This guide explores the foundational steps required to build a resilient triage layer that supports human decision-making without introducing systemic risk. Modern pipelines must prioritize high-signal data to maintain a competitive delivery cadence.
Improving CI Efficiency Through Intelligent Failure Analysis
Continuous Integration suites serve as the primary defense against regressions, yet their effectiveness is often hampered by the sheer volume of data they produce. When a suite returns dozens of failures, the initial response is typically a manual investigation to determine which failures are unique. This phase of the development lifecycle represents a significant drain on resources, as highly skilled engineers are relegated to performing basic pattern matching that could be handled more effectively by specialized algorithms.
Transitioning toward an intelligent analysis model involves moving away from the binary “pass or fail” mentality and adopting a more nuanced view of suite health. Automated systems can now aggregate disparate data points—such as stack traces, log entries, and deployment histories—to present a cohesive narrative of why a failure occurred. This shift not only accelerates the feedback loop for developers but also ensures that critical defects are not buried under a mountain of intermittent environmental issues or flaky test results.
Why Automating Test Triage Is Essential for High-Velocity Teams
Relying on manual triage creates a persistent bottleneck in the delivery pipeline, often consuming several hours of engineering time every morning. Automating this process ensures that the transition from failure detection to resolution is seamless and data-driven. One of the primary benefits is a drastic increase in efficiency, turning a 90-minute triage session into a 20-minute review of summarized findings.
Moreover, automated systems facilitate faster recovery times by rapidly identifying whether a failure is a genuine defect, a flaky test, or a temporary infrastructure outage. This immediate clarity allows release managers to make informed decisions regarding rollbacks or hotfixes without waiting for a manual audit of every red row. Reducing the cognitive load on the team is equally vital; AI-driven summaries consolidate scattered evidence into a single, readable view, which prevents the burnout associated with repetitive log analysis.
From a resource management perspective, automated triage offers economic scalability. By clustering failures before they are processed by large language models, teams can minimize token usage and keep operational costs negligible. This tiered approach ensures that the intelligence layer is only applied to unique problem sets rather than redundant instances of the same error, making the system viable for even the most extensive enterprise test suites.
Establishing a clear distinction between execution and analysis allows teams to scale their testing efforts without a linear increase in triage overhead. As the complexity of distributed systems grows, the ability to automatically parse and interpret failure patterns becomes a prerequisite for maintaining a high-velocity deployment schedule.
Best Practices for Building an AI-Powered Triage System
Implementing a triage automation layer requires a balanced approach between deterministic logic and generative intelligence. The most effective systems do not rely solely on AI to interpret every failure but instead use traditional programming techniques to organize data before passing it to a model. This structured pipeline ensures that the information provided to the intelligence layer is relevant, concise, and formatted for maximum accuracy.
A successful implementation treats the AI as a high-level reasoning engine that operates on pre-processed data. This prevents the common pitfalls of direct-to-AI pipelines, such as excessive latency and high operational costs. By establishing a rigid framework for data collection and normalization, organizations can ensure that their triage tools remain reliable even as the underlying software architecture evolves.
Implement Deterministic Clustering Before AI Processing
The first step in reducing noise within a CI pipeline is grouping identical failures using string normalization and hashing. Most failures in a large-scale regression suite are duplicates caused by the same underlying issue, such as a broken database connection or a shared service outage. By collapsing these duplicates before they reach the AI processing stage, teams can avoid redundant analysis and improve the accuracy of the resulting summaries.
Using deterministic logic for initial clustering is far more efficient than relying on an AI model to recognize patterns. Simple techniques like removing timestamps, unique identifiers, and memory addresses from stack traces allow for a consistent “fingerprint” of each failure. This grouping ensures that the intelligence layer only has to analyze a few unique failure shapes rather than hundreds of individual instances, significantly streamlining the entire workflow.
Reducing 60 Failures to 6 Distinct Clusters
In a typical large-scale regression run, a suite might return 60 red rows that initially appear to be distinct problems. However, after applying string matching and hashing to the stack traces, these 60 failures often collapse into as few as 6 distinct clusters. This process ensures the AI model only analyzes 6 unique failure profiles, preventing it from becoming overwhelmed by redundant data that adds no new information to the diagnostic process.
By focusing on these representative samples, the system can provide a much deeper analysis of the root cause for each group. This reduction in volume also simplifies the developer experience, as they are presented with 6 summarized issues rather than a daunting list of 60 individual failures to investigate. The goal is to provide a clear overview of the “shape” of the regression rather than a raw count of every failing assertion.
Enrich Clusters with Targeted Evidence and Strict Limits
Once failures are clustered, the system should automatically pull relevant logs, deployment history, and recent ticket data to provide context for the AI. It is vital to set hard limits on the amount of evidence gathered to avoid exceeding the context windows of modern language models. Excessive noise can lead to degraded performance, as the model may struggle to distinguish between relevant error messages and routine background logs.
Data enrichment should be surgical, focusing on the specific window of time when the failure occurred and the specific services involved. Pulling too much information can lead to “context bloat,” where the AI spends its processing power on irrelevant details. By curating the evidence fed into the model, teams ensure that the output remains focused on actionable insights rather than general observations about the system state.
Using Representative Sampling to Prevent Context Bloat
Implementing a constraint on log retrieval is a critical best practice for maintaining model precision. For example, setting a limit of 5 representative log lines per cluster provides enough context to identify the error without overwhelming the reasoning engine. This approach prevents the AI from generating vague or overly broad summaries that can happen when it is forced to process hundreds of lines of “noisy” infrastructure logs.
By providing only the most relevant timestamps and error messages, the model can maintain high precision in its root cause analysis. This sampling method ensures that the diagnostic tool remains fast and cost-effective while still delivering the context necessary to identify service outages or environmental misconfigurations. It represents a shift toward quality of data over quantity, which is essential for reliable automation.
Constrain AI Output with Strict Schemas and Enumerations
To prevent the AI from fabricating non-existent services or impossible root causes, the prompt must be heavily constrained by strict schemas. Using structured formats like JSON and providing specific lists of known services forces the model to remain grounded in the actual architecture of the application. This prevents the model from providing plausible-sounding but entirely false diagnoses that can mislead engineering teams.
Forcing the model to cite specific evidence IDs for every claim it makes ensures that the summaries are verifiable. When a model must point to a specific log line or ticket ID to support its conclusion, the likelihood of hallucination decreases significantly. This creates a transparent link between the raw data and the final summary, allowing engineers to quickly verify the tool’s findings before taking action.
Preventing Hallucinations via Known-Service Injection
A highly effective method for maintaining accuracy is the injection of a known-services list directly from the deployment manifest into the AI prompt. This constraint forces the model to choose from a list of valid architectural components rather than guessing the name of a service based on a stack trace. It eliminates the risk of the tool attributing a failure to a non-existent part of the system, which is a common issue with unconstrained generative models.
By aligning the AI’s “worldview” with the actual state of the infrastructure, teams can ensure that the diagnostic output is always relevant. This alignment is particularly important in microservice environments where service names can be similar and roles can overlap. Grounding the AI in the reality of the deployment ensures that its recommendations are actionable and trustworthy.
Validate AI Claims with an Automated Logic Gate
Before any AI-generated summary reaches a human reviewer, it should pass through an automated validation script. This logic gate checks that the test counts mentioned in the summary match the actual data and that every claim made by the AI refers to a valid piece of evidence. This secondary layer of verification acts as a safeguard against the inherent unpredictability of generative models.
The validation script serves as a filter that ensures only high-fidelity information is presented to the engineering team. If a claim cannot be verified against the source data, it should be flagged or discarded entirely. This rigorous approach to data integrity is what separates an experimental tool from a production-ready system that teams can rely on for critical release decisions.
Dropping Invalid Claims to Protect Human Trust
Automatically discarding any AI claim that cites non-existent evidence is essential for maintaining the team’s trust in the automated system. While this may occasionally result in a lower volume of information, it ensures that every detail an engineer sees is 100% verifiable. High trust in the tool’s accuracy is necessary for its long-term adoption; if users frequently encounter false information, they will quickly revert to manual triage methods.
Ensuring that the automated summary is always grounded in reality allows engineers to use it as a starting point for their investigations rather than a source of confusion. The validation layer acts as a quality control mechanism that protects the developer experience from the potential downsides of AI integration. In the long run, a smaller amount of accurate information is always more valuable than a large volume of unverifiable claims.
Strategic Implementation and Final Recommendations
The implementation of automated CI triage was designed to enhance human judgment rather than replace it entirely. Successful organizations treat the AI as a sophisticated, read-only assistant that prepares data for final human verification. This approach ensures that the responsibility for the release remains with the engineering team while the mechanical burden of data collection is handled by automation.
The transition toward automated triage enabled organizations to reclaim significant portions of their development cycles by filtering out environmental noise. Teams found that pinning AI model versions was necessary to prevent silent degradation caused by unannounced updates from service providers. Furthermore, the integration of strict validation gates allowed the system to remain a reliable source of truth even as the scale of the testing suites increased. The strategic value of this automation lay in its ability to transform a chaotic dashboard of failures into a structured list of understood issues. By the end of the initial rollout phase, the process of triage evolved into a rapid review of high-confidence summaries. This shift facilitated a more proactive approach to quality assurance, where defects were addressed based on their impact rather than their order in a log file. Organizations that adopted these practices reported a consistent improvement in pipeline stability and a reduction in the time required to achieve a green build status.