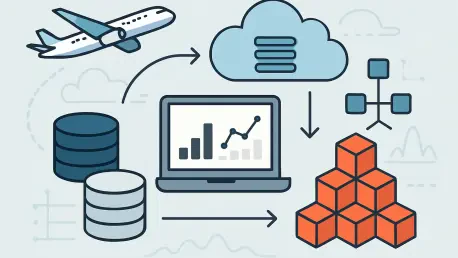
Aerospace organizations frequently struggle to unlock sensor-derived telemetry that remains trapped within specialized proprietary formats incompatible with standard analytics engines. This technical isolation often hinders critical safety analysis and operational improvements, as the data remains siloed in binary archives. Eclipse Aerospace, a prominent manufacturer of light jets, serves as a quintessential example of this pervasive industry challenge. With nearly twenty years of flight history—amounting to over a million flight hours and three terabytes of telemetry—the company possessed a treasure trove of data that was largely inaccessible due to its proprietary nature. The telemetry was sourced from satellite feeds and bulk uploads from flight decks, all encoded in formats that required highly specific, custom-built decoders. This created a massive bottleneck where raw binary files sat idle, waiting for specialized engineers to manually process them, while service centers and safety boards lacked the immediate insights required for real-time decision-making. The gap between data collection and data utility became an operational liability, necessitating a complete modernization of the ingestion pipeline to ensure that two decades of institutional knowledge could finally be converted into actionable intelligence within a unified cloud environment.
The Limitations: Legacy Data Ingestion Patterns
Before the shift toward modern data architectures, organizations typically relied on several suboptimal strategies for decoding proprietary telemetry, each presenting unique risks. One common approach involved utilizing Python User-Defined Functions (UDFs) within a distributed computing environment. While Python is favored for its readability and ease of implementation, UDFs are notoriously memory-intensive and often struggle with the variable-length nature of flight messages. For aerospace engineers, this technical debt frequently manifested as out-of-memory errors that crashed ingestion pipelines during peak processing times. The volatility of these functions meant that large batches of telemetry were often delayed, as the infrastructure struggled to balance the heavy computational load of decoding raw binary streams with the memory constraints of traditional executors. Consequently, the reliance on UDFs created a fragile ecosystem where technical stability was constantly at odds with the need for deeper data exploration and diagnostic speed.
Another traditional method used by established manufacturers involved the “Lambda and Avro” path, where external microservices were deployed to handle the decoding process before data ever reached the analytics engine. In this scenario, raw binary data was first processed via cloud functions, converted into a standard format like Avro, and then stored again before being picked up by the primary data platform. While functional, this multi-hop architecture introduced systemic inefficiencies that slowed down the entire engineering lifecycle. The redundant storage of both the original binary files and the converted Avro files essentially doubled storage costs, while the separation of the decoding logic from the main pipeline led to “schema drift.” When the aircraft sensors were updated, engineers had to update logic in multiple disconnected environments, leading to observability gaps where failures in the cloud functions were difficult to trace from the central data platform. This fragmented approach ultimately obscured the lineage of critical flight data and created unnecessary complexity for teams attempting to maintain a single source of truth.
Technological Breakthrough: PySpark and Apache Arrow
The release of Apache Spark 4.0 introduced the PySpark Custom Data Source API, representing a fundamental shift in how complex data is handled at scale. This innovation allowed engineering teams to register custom file formats directly within the Python environment, removing the historical need for complex Java Virtual Machine (JVM) connectors or the manual management of JAR files. By enabling the definition of read and write logic through native Python interfaces, the platform significantly reduced the friction associated with non-standard data types. Organizations were finally able to treat their proprietary binary telemetry with the same ease and flexibility as standard CSV or Parquet files. This architectural simplification meant that the logic required to parse complex aerospace data could be integrated directly into the Spark engine, allowing for a more cohesive and manageable ingestion process that aligned with modern DevSecOps practices and continuous integration workflows.
While the Python API provided the necessary orchestration layer, its true power was realized through its deep integration with the Apache Arrow format. Apache Arrow serves as a language-independent columnar memory format that enables different programming languages to share data objects without the massive overhead associated with serialization or data copying. This “zero-copy” capability allowed engineers to use Python as a control layer for managing the ingestion pipeline while delegating the heavy computational lifting of binary decoding to highly efficient, compiled languages. By leveraging the Arrow C Data Interface, the system could move data across the Foreign Function Interface (FFI) boundary with negligible latency. This synergy ensured that even the most complex telemetry formats could be ingested at native speeds, providing a bridge between the flexible development environment of Python and the raw performance required for processing terabytes of sensor data in real time.
System Integration: Rust and Databricks Serverless
The modernization of flight data ingestion required a sophisticated architecture that combined the safety and speed of Rust with the scalability of Databricks Serverless. In this model, the core decoding logic was encapsulated within a dedicated Rust crate, which remained entirely independent of the Spark environment. This separation of concerns allowed the engineering team to reuse existing, highly optimized Rust software development kits that had been battle-tested in other aerospace applications. By taking raw bytes directly from the aircraft’s storage and returning structured records, the Rust-backed decoder provided a high-performance foundation that was immune to many of the memory safety issues found in other systems. The implementation effectively decoupled the intricate business logic of flight telemetry from the distributed processing framework, resulting in a cleaner, more maintainable codebase that could be versioned and tested with much greater precision.
To achieve maximum operational efficiency, the entire pipeline was deployed on Databricks Serverless compute, which automatically allocated resources based on the specific demands of the ingestion task. This eliminated the financial and operational burden of managing “always-on” clusters that often sat idle between flight data uploads. The serverless environment provided the responsiveness of a dedicated system without the associated overhead, allowing the platform to scale up instantly when a large batch of telemetry arrived and scale back down as soon as the processing was complete. This elastic approach was particularly beneficial for aerospace organizations that experienced sporadic data arrivals from different time zones and satellite links. By combining the high-speed execution of Rust decoders with the on-demand availability of serverless infrastructure, the system provided a robust, cost-effective solution that ensured flight data was always ready for analysis without requiring constant human intervention.
Performance Metrics: Realizing Quantifiable Operational Gains
The transition to a Rust-backed implementation via the Apache Arrow framework delivered performance gains that fundamentally changed the speed of aerospace analytics. Benchmarks conducted during the modernization process indicated that this new approach was twice as fast as similar implementations using pure-Python PyArrow sources, which are already considered highly efficient. Even more striking was the comparison to standard native Python implementations that did not utilize the Arrow framework; the modernized architecture provided nearly twenty times the performance. These improvements were not merely incremental; they represented a paradigm shift in how quickly raw sensor data could be transformed into meaningful engineering metrics. The reduction in computational overhead meant that the system could handle higher levels of concurrency, allowing multiple flight datasets to be processed simultaneously without degrading the performance of the overall analytics platform.
For practical flight operations, these technical benchmarks translated into a dramatic reduction in the “time-to-insight” for engineering and maintenance teams. Large, multi-gigabyte batches of flight history that previously required extensive manual pre-processing or hours of compute time could now be handled in parallel in under two minutes. Smaller, more recent telemetry files were often available for detailed analysis within sixty seconds of being uploaded to the cloud environment. This rapid turnaround allowed aerospace engineers to review aircraft performance and identify potential maintenance issues almost as soon as the data was received from the aircraft. The ability to process nearly two decades of historical data in a fraction of the time also enabled more comprehensive long-term trend analysis, allowing the organization to uncover patterns in component wear and fuel efficiency that were previously obscured by the slow pace of legacy ingestion systems.
Unified Ingestion: Why Native Integration Wins
The shift toward native integration within the Spark engine represents a strategic departure from the fragmented ingestion patterns that once dominated the industry. By collapsing the data pipeline from a multi-stage sequence of external microservices into a single, Spark-native read operation, organizations removed the network hops and queuing delays that traditionally plagued telemetry processing. This “single-hop” architecture allowed the data to flow directly from the binary source file into the Delta table, ensuring that the information remained within a secured and governed environment throughout its entire lifecycle. The reduction in moving parts simplified the overall system design, making it easier for data engineers to maintain the pipeline and reducing the number of potential failure points. This streamlined approach not only accelerated the ingestion process but also ensured that the data was consistently formatted and ready for high-level machine learning and predictive modeling tasks.
Furthermore, native integration significantly enhanced the observability of the entire data ecosystem, providing engineers with a centralized view of all ingestion activities. Because the decoding step became a native Spark stage, every detail of the process was fully visible within the Spark UI, allowing for granular monitoring of job metrics and execution stages. When a failure occurred, data engineers could debug the issue within a single platform rather than searching through disconnected logs across various cloud services. The implementation of a “bad records” logic allowed the system to automatically isolate malformed or corrupted telemetry without crashing the entire ingestion job, ensuring that the pipeline remained robust even when handling data from older or malfunctioning sensors. This level of transparency and reliability transformed the data ingestion process from a mysterious “black box” into a predictable, manageable component of the broader aerospace intelligence framework.
Strategic Implementation: Maximizing Efficiency and Visibility
Maximizing cost efficiency in modern data pipelines required a fundamental reevaluation of storage and compute strategies. By removing the need for intermediary file formats like Avro, aerospace organizations were able to eliminate the redundant storage costs that had accumulated over years of operations. This direct-to-Delta approach meant that the only persistent storage required was for the original binary source files and the final, structured tables used for analytics. Furthermore, the use of serverless compute ensured that the organization only paid for the exact CPU cycles used during the active decoding and ingestion process. This move away from static, dedicated infrastructure allowed for a more precise alignment between IT spending and actual data utilization, providing a clear financial incentive for modernizing legacy systems. The resulting savings could then be reinvested into more advanced analytics projects, such as predictive maintenance algorithms or flight path optimization models.
Beyond the immediate financial benefits, the modernization effort significantly boosted engineering productivity by creating a more agile development environment. The “Single Source of Truth” principle was applied to the data schema itself, which was defined once within a versioned connector rather than being duplicated across multiple microservices. This reduction in logic drift simplified the development lifecycle, allowing teams to deploy updates to the ingestion logic with greater confidence and speed. The modular nature of the Rust and Python integration also meant that the same underlying framework could be reused for other proprietary formats, such as HDF5 or ARINC 429, which are common across the aerospace and defense sectors. This reusability ensured that the organization could quickly adapt to new data sources or aircraft models without having to rebuild their entire ingestion infrastructure from scratch, creating a future-proof foundation for ongoing innovation.
Future Perspectives: Unlocking Specialized Data Potential
The methodology developed for modernizing flight telemetry is directly applicable to a wide range of specialized industries that rely on complex binary data formats. Whether in high-tech manufacturing, where sensor data from the factory floor is often trapped in proprietary PLC formats, or in life sciences, where high-resolution imaging data requires specialized decoding, the combination of native Spark integration and high-performance compiled logic provides a universal blueprint for data accessibility. Organizations that adopted these techniques moved beyond the limitations of legacy “multi-hop” architectures and embraced a unified approach that prioritized speed, visibility, and cost-effectiveness. By standardizing the ingestion process through open memory formats like Apache Arrow, these companies ensured that their data remained portable and accessible to a variety of downstream analytics tools and artificial intelligence frameworks, regardless of the original source format.
In the final assessment, the modernization of flight data ingestion proved to be a transformative initiative for the aerospace sector. Engineers successfully bridged the gap between twenty years of inaccessible binary archives and the modern need for high-speed, actionable intelligence. The transition to a Rust and Arrow-backed Spark source eliminated the operational bottlenecks that once hindered safety analysis and maintenance scheduling. Service centers were empowered with faster access to critical flight metrics, while the overall cost of data management was significantly reduced through the elimination of redundant storage and the adoption of serverless compute. For organizations looking to replicate this success, the path forward involves a strategic focus on native integration and the use of polyglot programming to balance development ease with raw execution speed. This unified approach not only solved the immediate challenge of data ingestion but also created a scalable platform for the next generation of aerospace analytics.